How to Accurately Convert PDF Content Into Structured JSON With Apryse IDP Data Extraction
What if data extraction would "just work", right out of the box - without training the model on each document type, or having to check for errors?
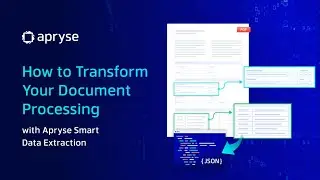
Apryse IDP's new Intelligent Data Extraction marks a milestone advancement in the accuracy and efficiency of processing data, text, tables, and content from PDF documents right into your database or workflow.
Highlights:
Extract PDF content into a structured JSON file to use in subsequent workflows
Out-of-the-box data extraction that “just works” without the need to program countless templates for all possible layout variations
Accurately and reliably detect tables in PDF documents and extract information to your database
Blog: Release Overview - "PDF to Structured JSON":
https://apryse.com/blog/introducing-a...
Blog: How JSON extraction benefits organizations:
https://apryse.com/blog/put-idp-and-p...
Documentation:
https://docs.apryse.com/documentation...
Nesta página do site você pode assistir ao vídeo on-line How to Accurately Convert PDF Content Into Structured JSON With Apryse IDP Data Extraction duração hora minuto segundo em boa qualidade , que foi baixado pelo usuário Apryse 17 Fevereiro 2023, compartilhe o link com seus amigos e conhecidos, no youtube este vídeo já foi visto 4,167 vezes e gostou 29 espectadores. Boa visualização!